Data pipeline management involves designing, building, and maintaining systems that move data efficiently and reliably. This process ensures that businesses can access accurate and timely data for critical decision-making. Without it, organizations face challenges like inconsistent data quality, integration complexities, and scalability issues.
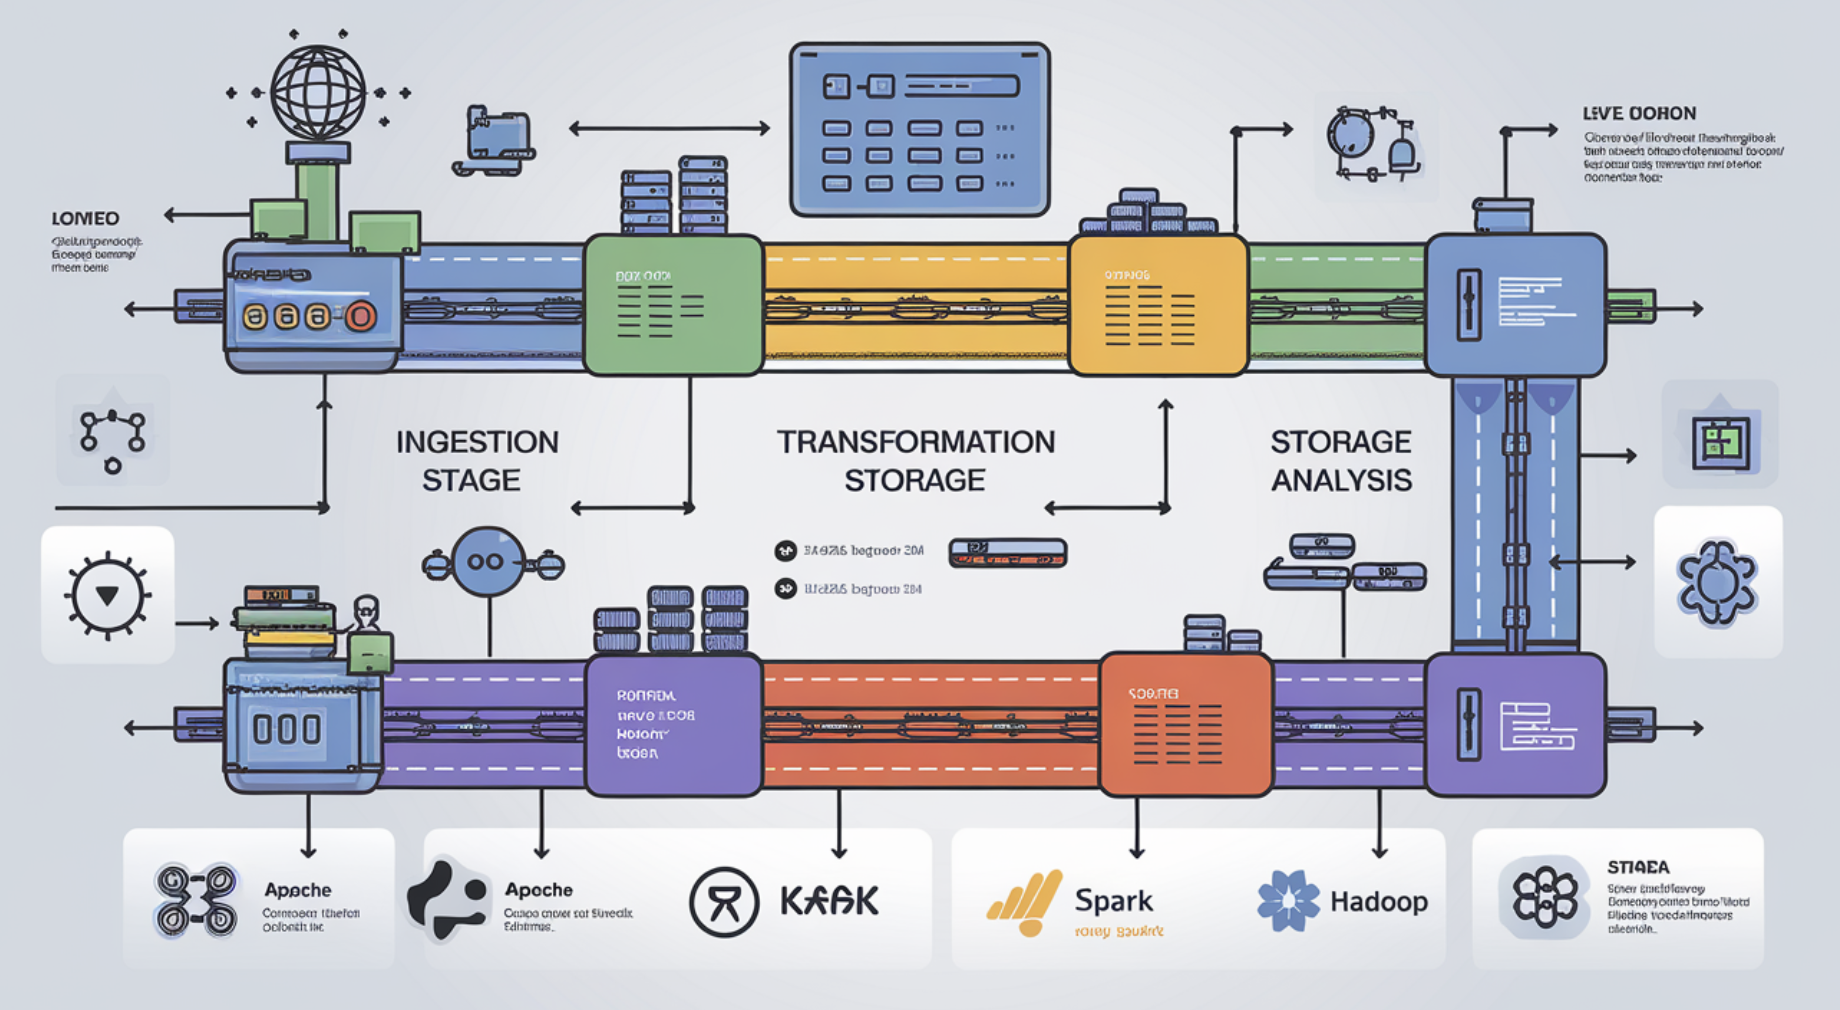
The growing importance of data management is evident. The global data pipeline tools market, valued at $6.8 billion in 2021, is projected to reach $35.6 billion by 2031, with a CAGR of 18.2%. This growth highlights how businesses increasingly rely on robust data systems to optimize operations and stay competitive.
Key Takeaways on Data Pipeline Management
- Managing data pipelines ensures fast, safe data flow for better decision-making.
- Automation and regular checks improve pipeline efficiency and data accuracy.
- Tools like FineDataLink help scale pipelines to meet growing business needs.
What is a Data Pipeline Management?
Definition of a Data Pipeline
A data pipeline is a system that moves data from one location to another while transforming and processing it along the way. It ensures that raw data becomes usable and accessible for analysis or decision-making. Think of it as a series of interconnected steps that collect, clean, and deliver data to its final destination. These pipelines are essential for handling the vast amounts of data generated daily, enabling you to extract meaningful insights efficiently.
Key Stages of a Data Pipeline
Every data pipeline consists of several critical stages that work together to ensure smooth data flow. Understanding these stages helps you appreciate how data pipelines function.
Data Sources
Data sources are the starting point of any pipeline. These can include databases, APIs, IoT devices, or even social media platforms. For example, a retail company might gather sales data from its point-of-sale systems or customer feedback from online reviews. The goal is to collect data from diverse origins to create a comprehensive dataset.
Data Processing
Once the data is collected, it undergoes processing to make it usable. This stage involves cleaning, transforming, and organizing the data. Tasks like removing duplicates, correcting errors, and standardizing formats occur here. For instance, if you’re analyzing customer data, this step ensures that names, addresses, and purchase histories are consistent and accurate.
Data Destinations
The final stage involves delivering the processed data to its destination. This could be a data warehouse, a business intelligence tool, or a machine learning model. For example, a healthcare organization might store patient data in a secure database for future analysis. The destination depends on how you plan to use the data.
Types of Data Pipelines
Data pipelines come in different forms, each suited to specific needs. The two primary types are batch processing pipelines and real-time processing pipelines.
Batch Processing Pipelines
Batch processing pipelines handle large volumes of data at scheduled intervals. They are ideal for tasks that don’t require immediate results. Industries like healthcare and retail often use batch processing to analyze historical data. For instance, a retail chain might process sales data overnight to optimize inventory levels the next day.
Real-Time Processing Pipelines
Real-time processing pipelines work continuously, processing data as it arrives. These pipelines are crucial for scenarios where immediate action is necessary. For example, financial institutions use real-time pipelines to detect fraudulent transactions instantly. This type of pipeline ensures that you can respond to changes as they happen.
| Criteria | Real-time data processing | Batch data processing |
|---|---|---|
| Data volume | Suitable for large data streams requiring immediate processing. | Suitable for low-volume data sets processed regularly. |
| Data speed | Handles high-speed data with rapid changes. | Processes low-velocity data with slow changes. |
| Data diversity | Ideal for diverse, unstructured data. | Best for homogeneous, structured data. |
| Data value | Supports high-value data impacting operations. | Suitable for low-value data indirectly affecting operations. |
Both types of pipelines play a vital role in modern data pipeline management, helping organizations meet their unique data needs.
Core Components of Data Pipeline Management
Data Ingestion
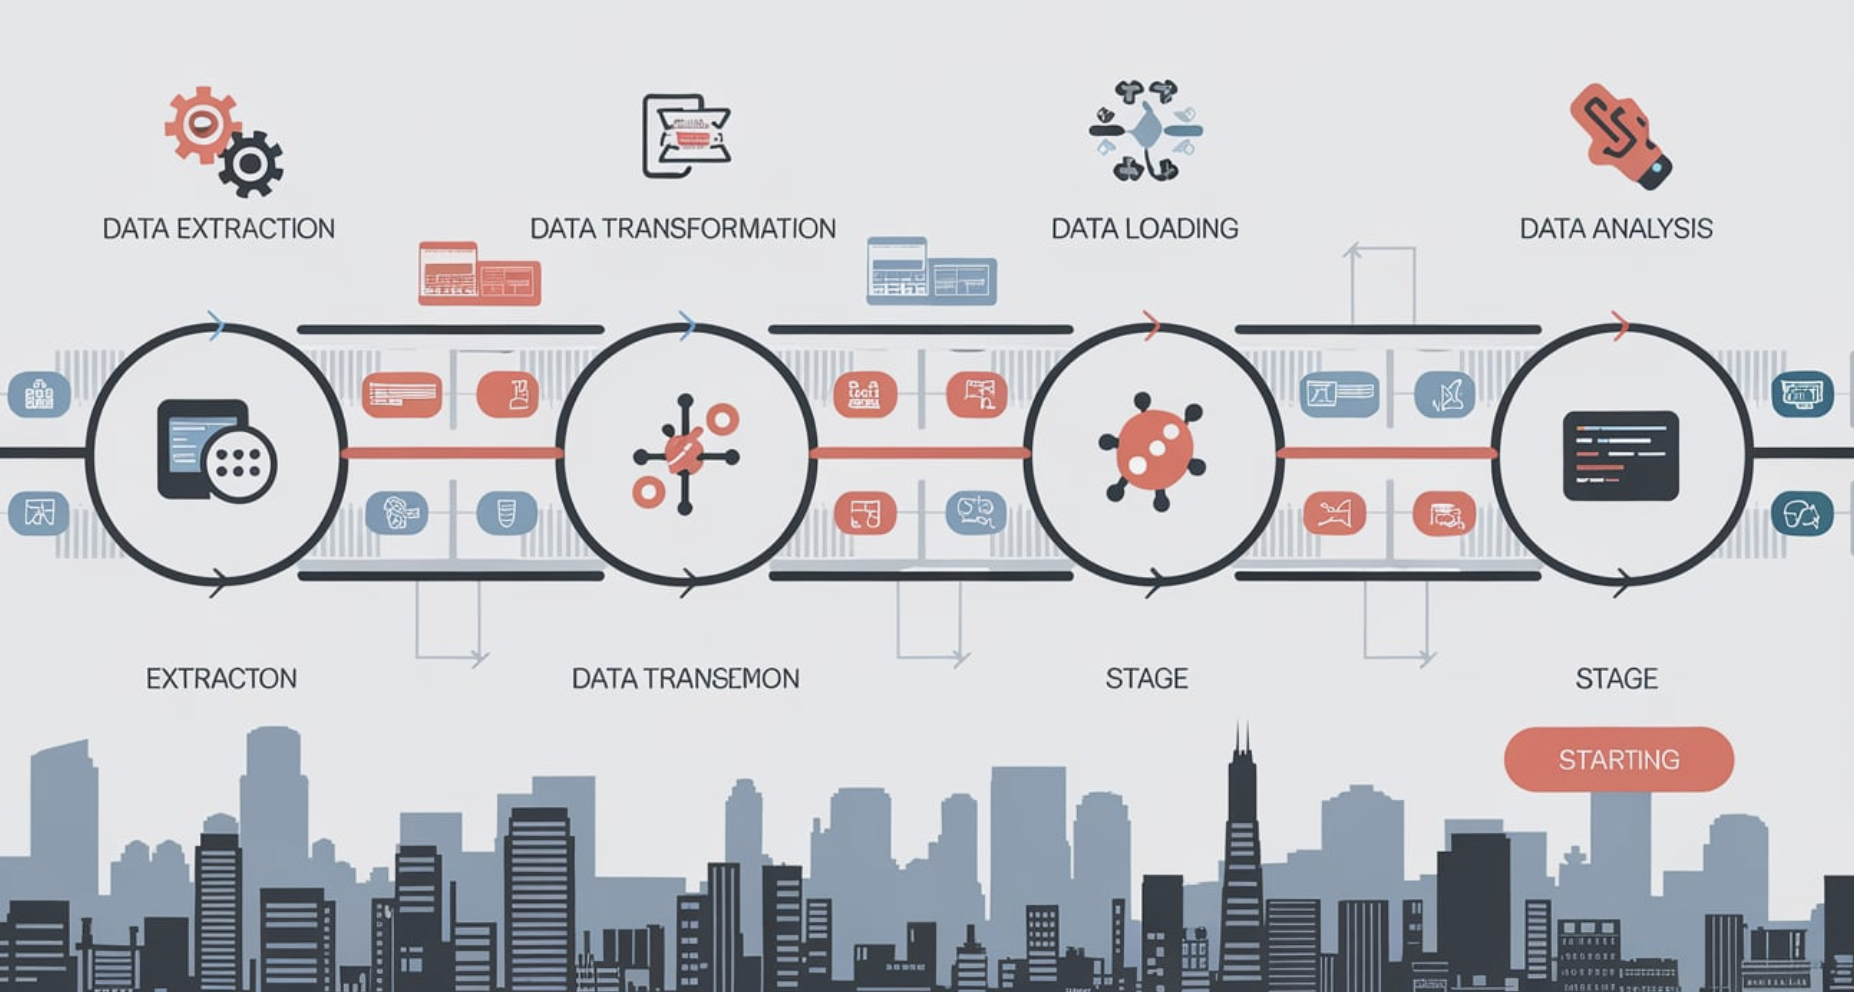
Data ingestion is the first step in any data pipeline management process. It involves capturing and importing data from various sources into the pipeline. You might collect data from internal systems like databases or external sources such as APIs, IoT devices, or social media platforms. This step ensures that raw data enters the pipeline for further processing.
To handle data ingestion effectively, you need to consider several factors:
- Capturing data in real-time or through batch processing, depending on your requirements.
- Adapting to the size and speed of incoming data to avoid bottlenecks.
- Collecting data from diverse sources using various protocols and formats.
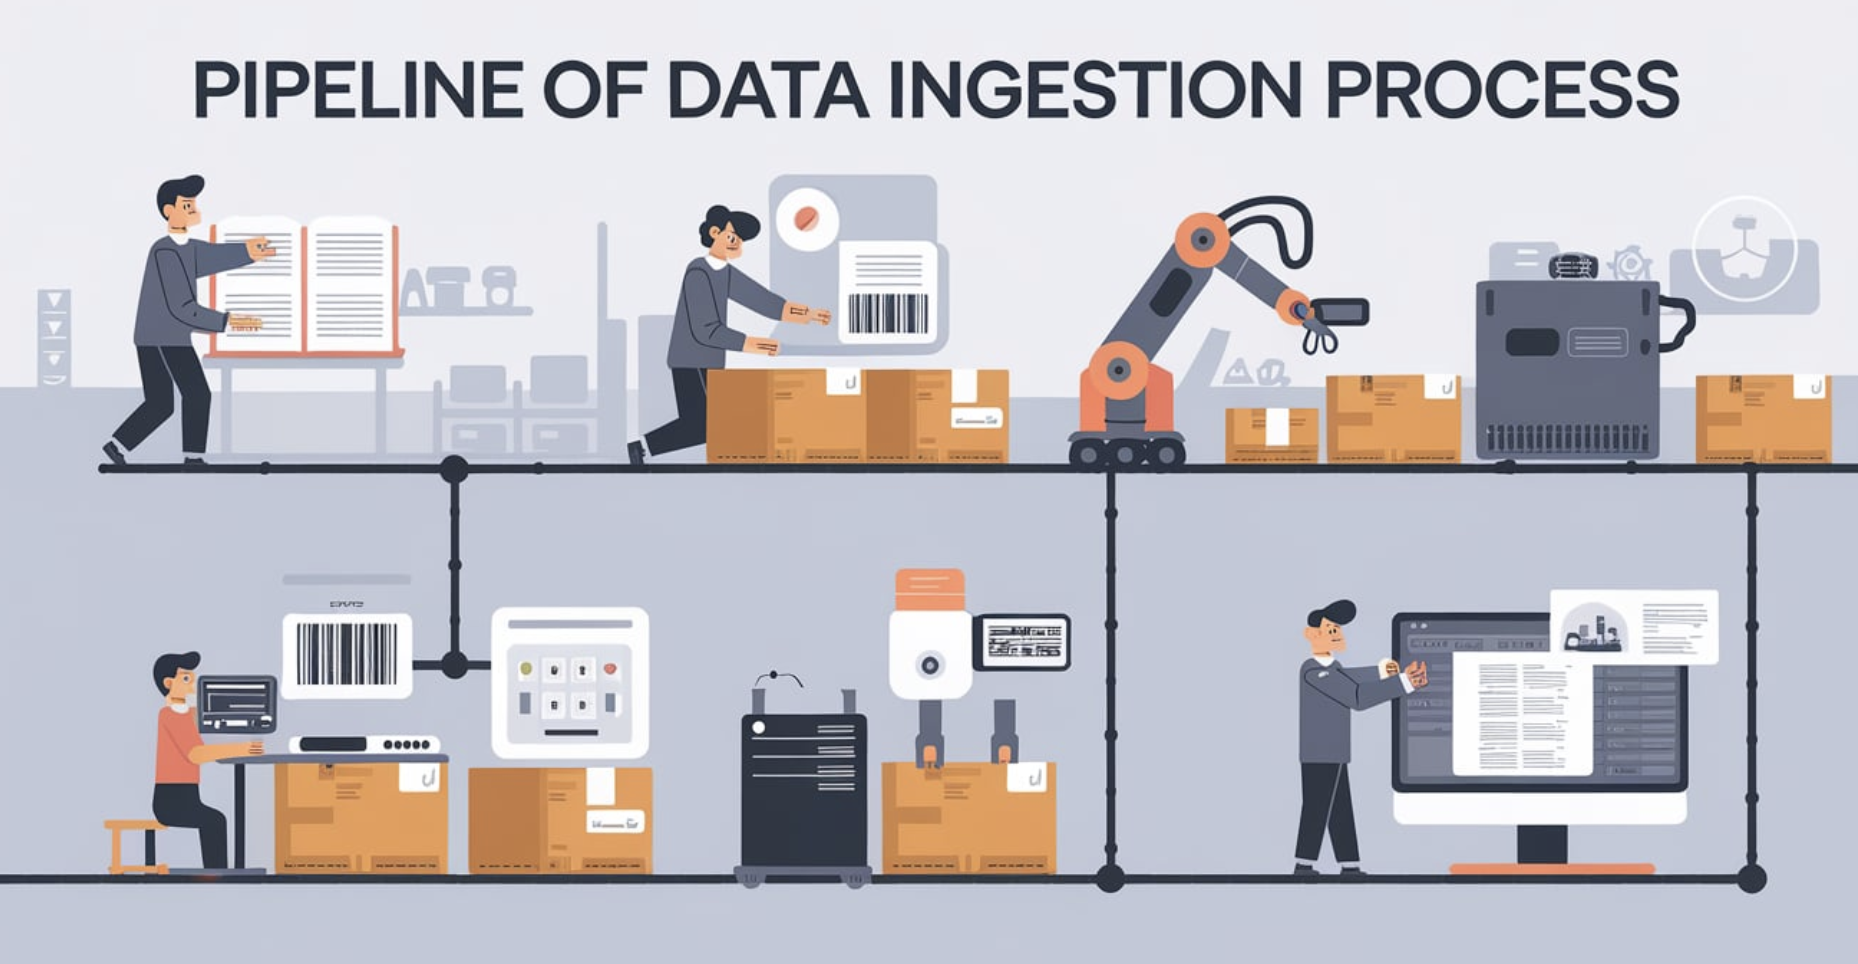
For example, a retail business might use data ingestion to gather sales data from point-of-sale systems and customer feedback from online reviews. By ensuring seamless data ingestion, you can create a strong foundation for the rest of the pipeline.
Data Transformation
Once data enters the pipeline, it undergoes transformation to make it usable. This stage involves cleaning, enriching, and structuring the data to meet your specific needs. Data transformation ensures that the information is accurate, consistent, and ready for analysis.
The process typically follows these steps:
- Data discovery: Identify the datasets relevant to your project.
- Data mapping: Match data sources to the destination based on your data model.
- Data extraction: Design the extraction phase for different data sources.
- Transform: Apply transformations like removing duplicates, standardizing formats, or enriching data with additional attributes.
- Review: Conduct manual or automated reviews to ensure data integrity.
- Loading: Load the transformed data into a data warehouse or other storage systems.
For instance, a healthcare organization might transform patient data by standardizing medical codes and removing errors. This step ensures that the data is reliable and ready for use in decision-making.
Data Storage
Data storage is the final component of data pipeline management. It involves storing processed data in a secure and scalable environment. The choice of storage depends on your business objectives and how you plan to use the data.
To ensure effective data storage, follow these best practices:
- Understand your business needs and choose the right technology stack.
- Design for scalability to accommodate future growth.
- Use modular architecture for flexibility.
- Implement automated testing and monitoring to maintain data quality.
- Leverage cloud technologies for cost-effective and scalable storage.
- Ensure robust security measures to protect sensitive data.
For example, a financial institution might store transaction data in a cloud-based data warehouse. This approach allows for real-time access and analysis while maintaining high security standards.
By focusing on these core components—data ingestion, transformation, and storage—you can build a robust data pipeline management system. This ensures that your data flows seamlessly from source to destination, enabling better decision-making and operational efficiency.
Data Monitoring and Maintenance
Monitoring and maintaining your data pipeline management system is essential for ensuring its efficiency and reliability. Without proper oversight, data pipelines can encounter issues like delays, errors, or even complete failures. These problems can disrupt your operations and compromise the quality of your data. By implementing robust monitoring and maintenance practices, you can keep your pipelines running smoothly and ensure consistent data flow.
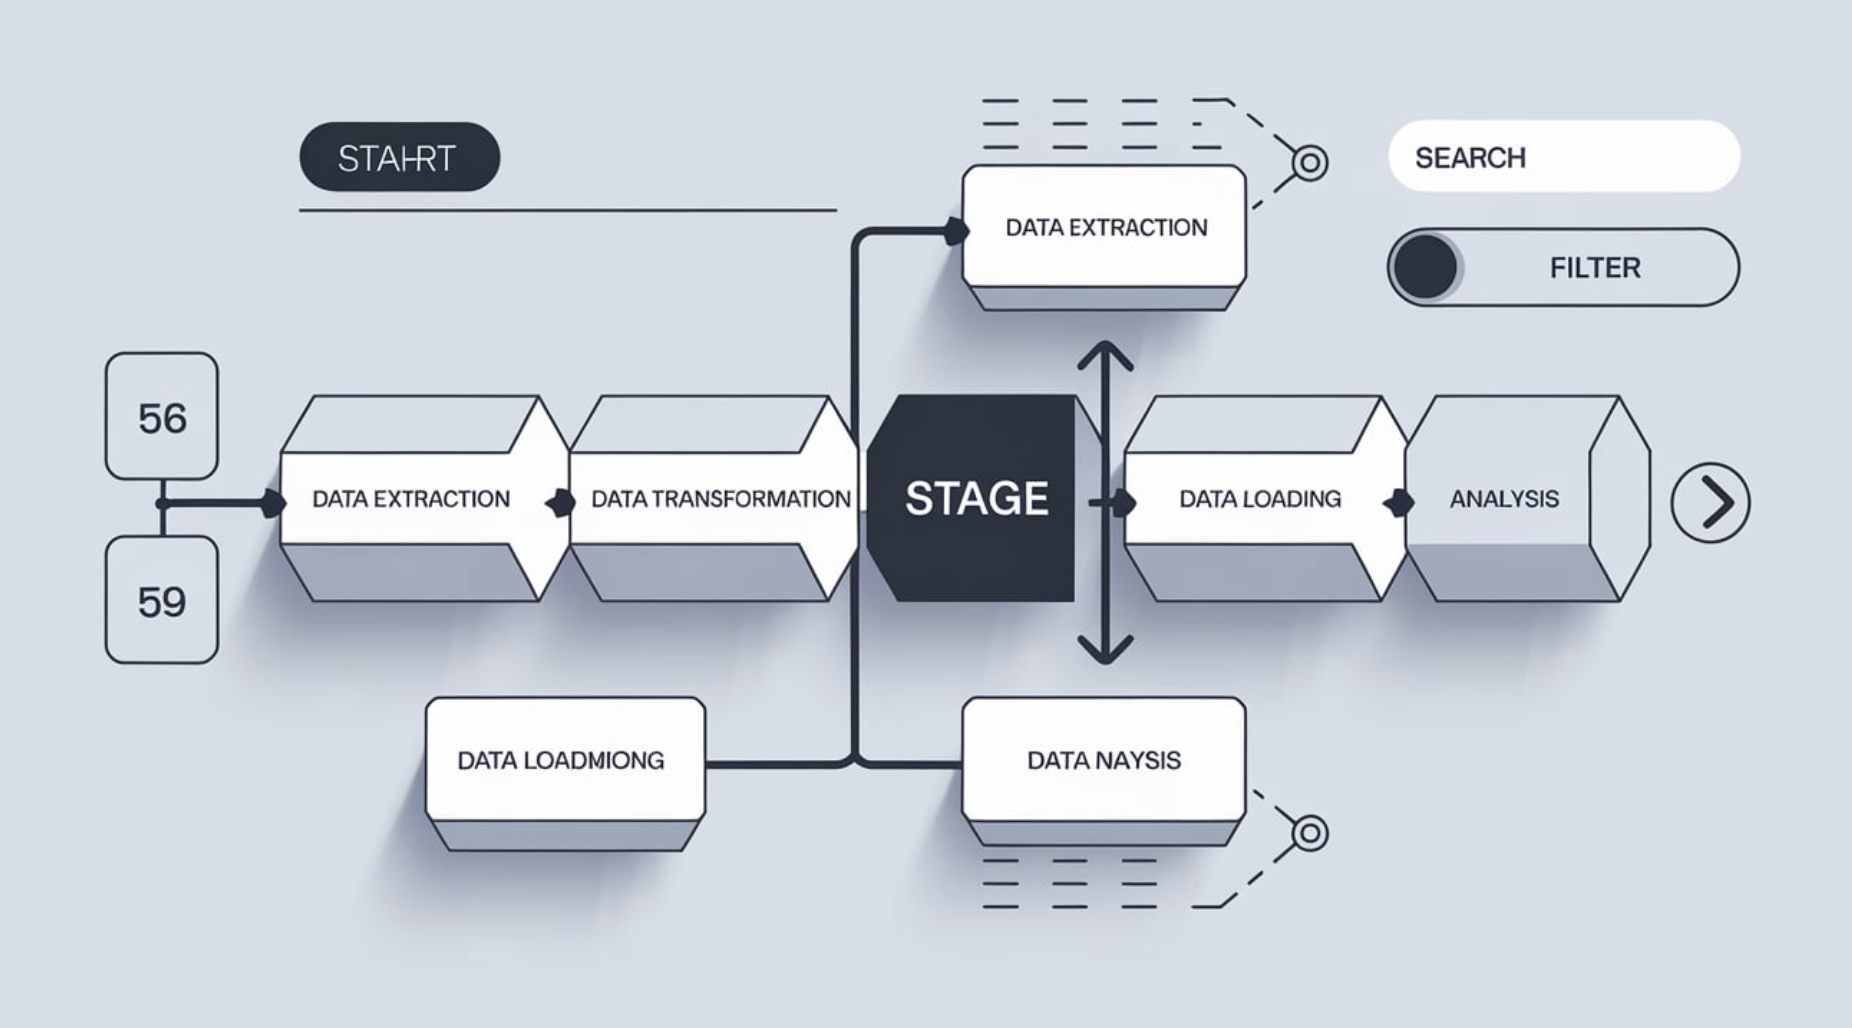
To monitor your data pipelines effectively, you need tools that provide visibility into data movement. These tools help you track how data flows through the pipeline and identify potential bottlenecks. For example, anomaly detection tools can alert you to performance issues and provide metrics to guide improvements. Data ingestion metrics also play a crucial role by tracking the performance of incoming data and helping you spot problems early.
Maintaining data quality is another critical aspect of data pipeline management. You can use various techniques to ensure your data remains accurate and reliable. Some of the most effective methods include:
- Completeness Checks: Verify that no critical data is missing from your pipeline.
- Uniqueness Tests: Ensure each record in your dataset is unique and free from duplicates.
- Validity Tests: Confirm that your data adheres to predefined formats or rules.
- Timeliness Checks: Make sure your data updates occur within the required timeframes.
These checks help you maintain high data quality, which is vital for making informed decisions.
Regular maintenance of your data pipelines involves proactive measures to prevent issues before they arise. You should schedule routine inspections to identify outdated components or inefficiencies. Updating your pipeline to accommodate new data sources or formats is equally important. By staying ahead of potential problems, you can minimize downtime and maintain seamless operations.
Incorporating these monitoring and maintenance practices into your data pipeline management strategy ensures that your system remains robust and scalable. Reliable pipelines not only improve operational efficiency but also enhance your ability to make data-driven decisions. With the right tools and techniques, you can build a resilient data infrastructure that supports your business goals.
How Data Pipeline Management Works
Ensuring Efficiency
Efficiency in data pipeline management ensures that your data flows seamlessly from source to destination without unnecessary delays or errors. By automating processes like data ingestion, transformation, and storage, you can eliminate manual errors and save valuable time. This automation allows you to focus on analyzing data rather than managing it.
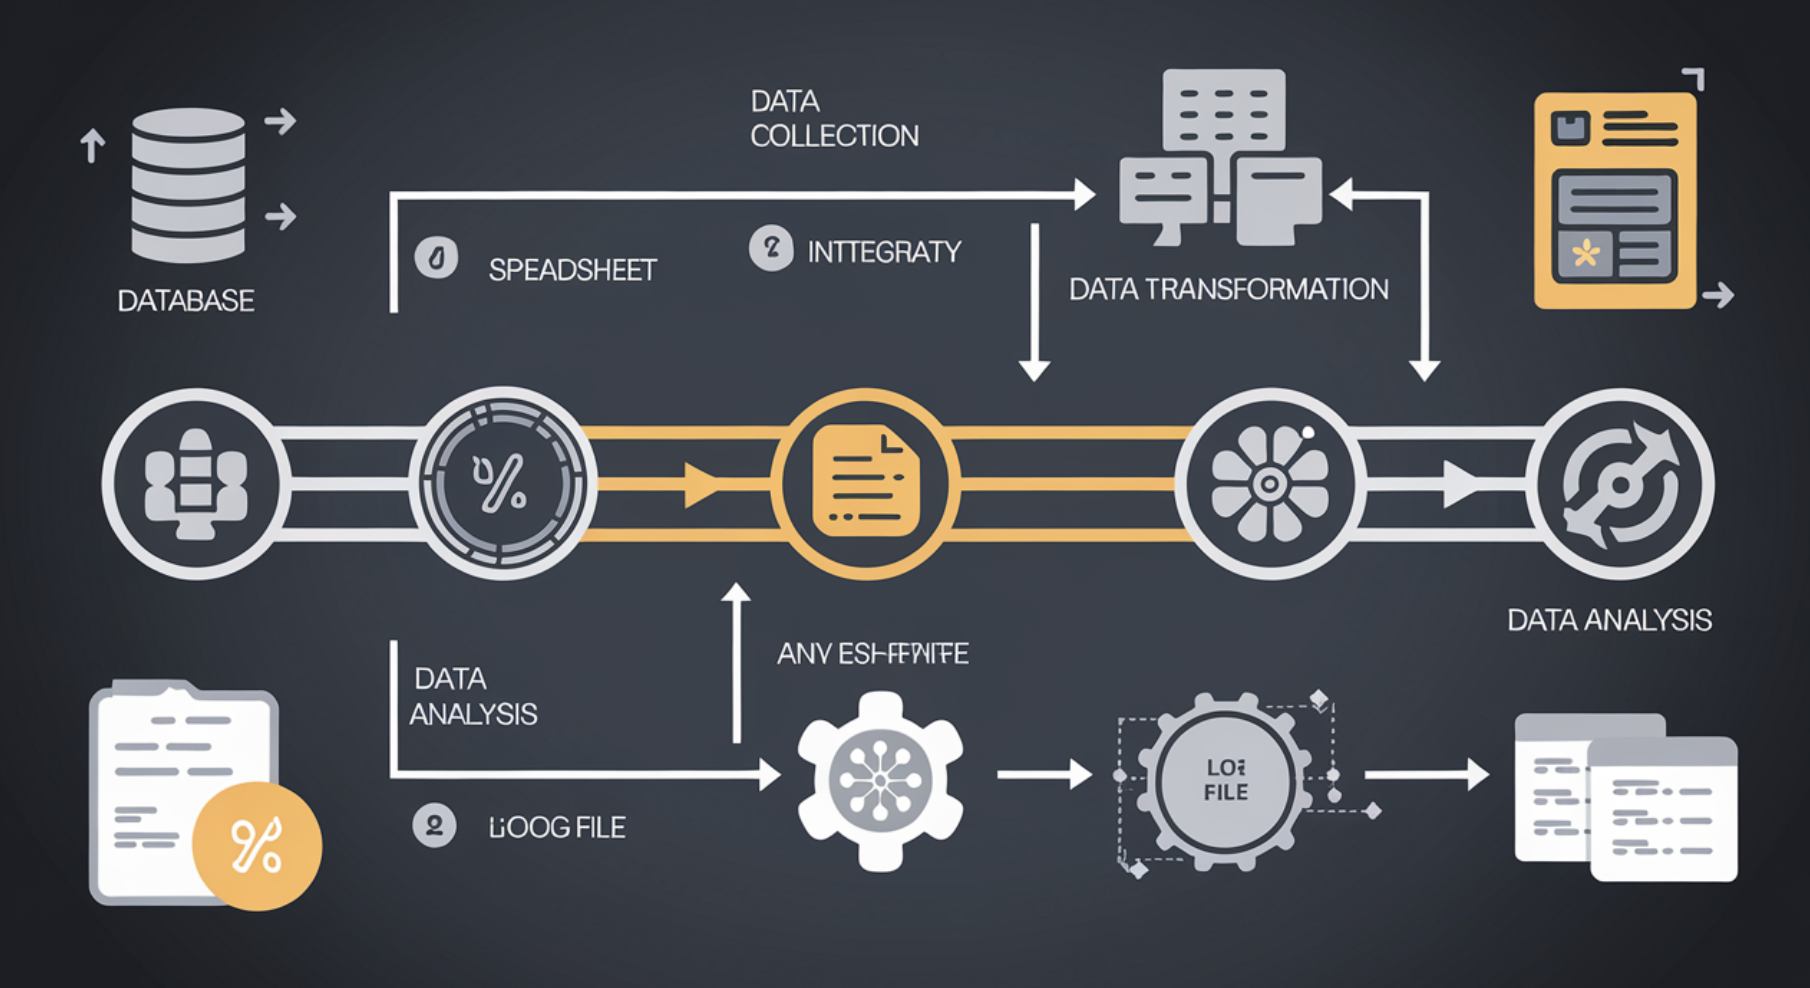
Several factors contribute to the efficiency of a data pipeline. These include:
| Component | Description |
|---|---|
| Data Ingestion | Acquiring data from sources using techniques like batch processing or real-time streaming. |
| Data Processing | Cleaning, enriching, and transforming data into a suitable format for analysis or storage. |
| Transformation | Converting data into a usable format for downstream applications, including handling missing values. |
| Data Storage | Storing processed data in systems like data warehouses or lakes based on organizational needs. |
| Orchestration | Managing the flow of data through various stages to ensure correct order and timing. |
| Monitoring and Logging | Continuous monitoring to identify issues and logging for debugging and optimization. |
| Error Handling | Mechanisms for gracefully handling errors, including retries and notifications. |
| Security and Compliance | Adhering to security standards and regulations, including data encryption and access controls. |
By focusing on these components, you can build a pipeline that is not only efficient but also scalable and reliable. For example, orchestration tools ensure that data flows in the correct sequence, while monitoring tools help you identify and resolve issues before they escalate.
Maintaining Reliability
Reliability in data pipelines ensures that your data remains accurate and accessible at all times. Without reliability, you risk flawed analytics and poor decision-making. To maintain reliability, you must address common challenges like data quality concerns and integration hurdles.
Data quality plays a critical role in reliability. Inaccurate or incomplete data can undermine your entire pipeline. Implementing robust validation and cleansing processes ensures that your data meets the required standards. For example, completeness checks verify that no critical data is missing, while uniqueness tests ensure that each record is free from duplicates.
Integration complexity is another challenge. Merging data from diverse sources often involves overcoming differing formats and standards. Using flexible integration tools can simplify this process. These tools allow you to connect various data sources seamlessly, ensuring a consistent flow of information.
Regular monitoring and maintenance also enhance reliability. By tracking data flow and addressing issues proactively, you can prevent disruptions and maintain a steady pipeline. For instance, anomaly detection tools can alert you to irregularities, enabling you to take corrective action immediately.
Scaling for Growth with FanRuan-en's FineDataLink
As your business grows, your data pipeline must scale to handle increasing volumes and complexity. FineDataLink, a product by FanRuan, offers a robust solution for scaling your data pipeline management. Its cloud-native architecture allows you to adjust resources on demand, ensuring consistent performance regardless of data volume.
FineDataLink supports real-time data synchronization, making it ideal for businesses that require immediate insights. Its low-code platform simplifies complex data integration tasks, enabling you to scale your pipeline without extensive technical expertise. For example, you can use its drag-and-drop functionality to build new pipelines quickly, saving time and effort.
The platform also enhances operational efficiency by providing advanced ETL/ELT capabilities. These features allow you to preprocess and transform data effectively, ensuring that your pipeline remains efficient as it scales. Additionally, FineDataLink supports over 100 data sources, giving you the flexibility to integrate diverse systems seamlessly.
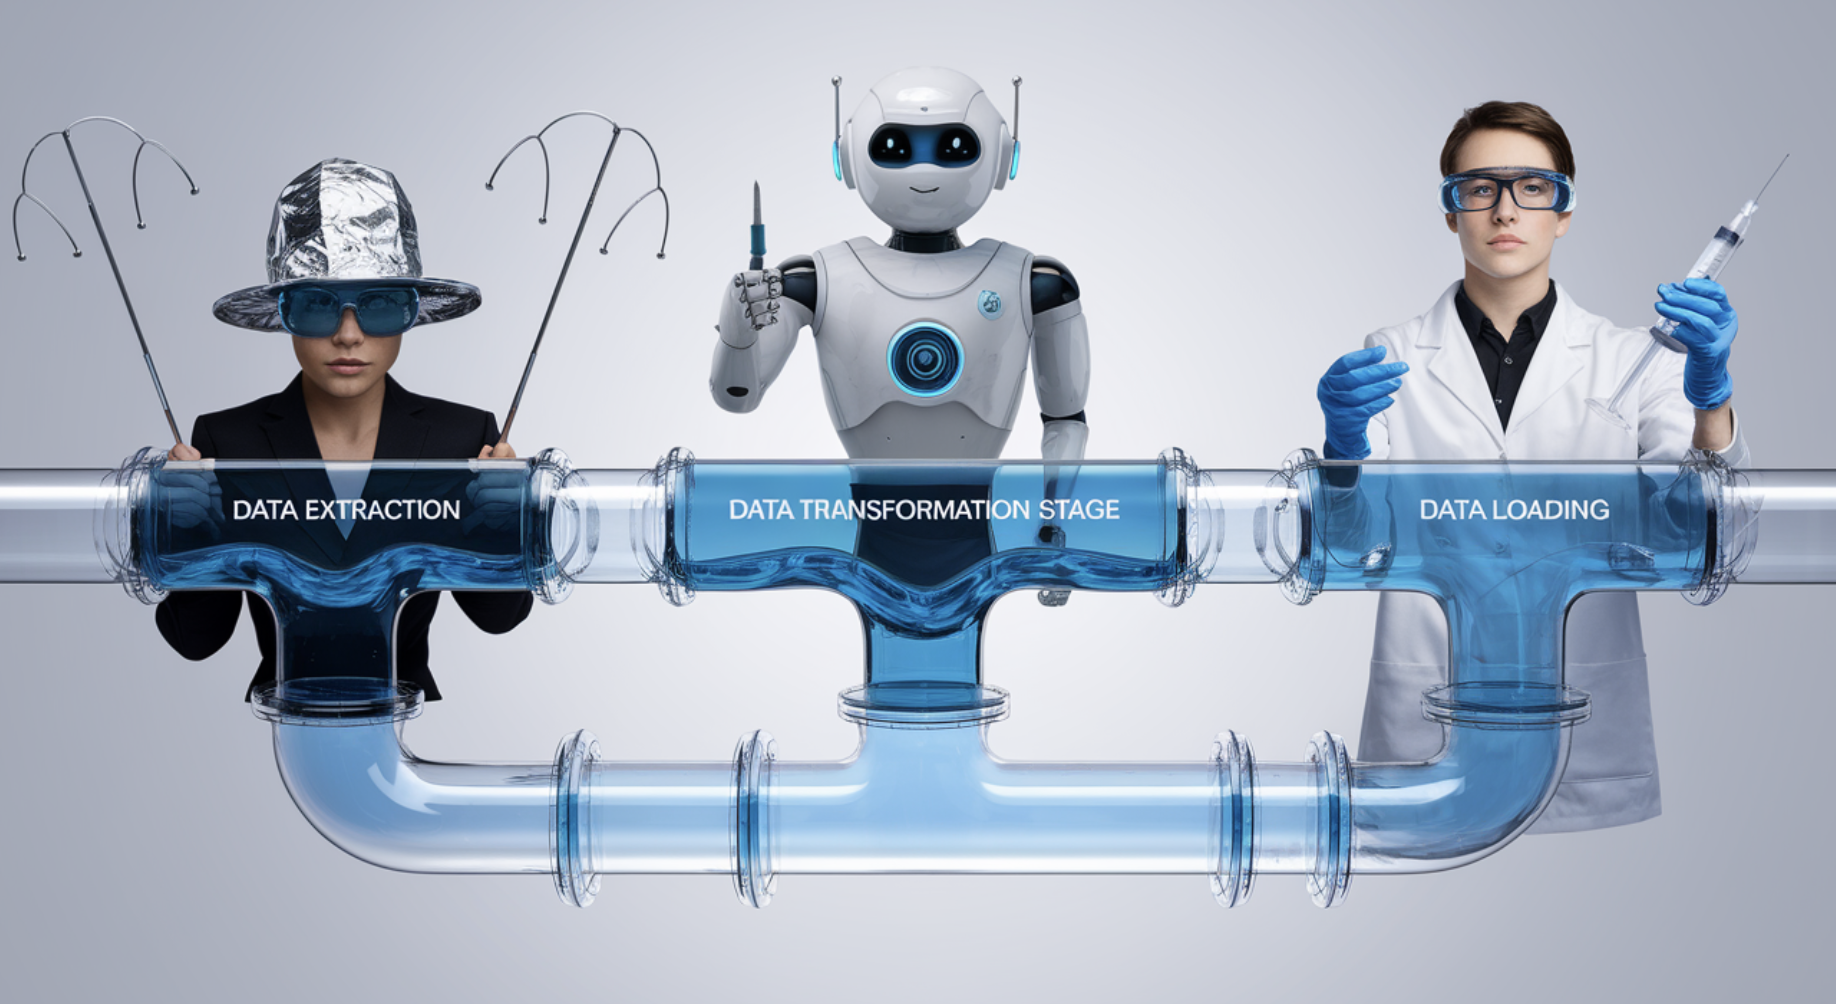
By leveraging FineDataLink, you can future-proof your data pipeline management. Its scalability ensures that your pipeline grows with your business, enabling you to maintain efficiency and reliability even as your data needs evolve.
Why Data Pipeline Management Matters
Importance of Reliable Data Flow
Reliable data flow forms the backbone of any successful data pipeline. When your data moves seamlessly through the pipeline, it ensures that critical information reaches its destination without delays or errors. This reliability is essential for maintaining trust in your data systems and avoiding disruptions in operations.
A well-managed data pipeline helps you overcome challenges like data overload and inconsistent data quality. By implementing robust data management strategies, you can ensure that essential insights remain accessible for timely decisions. Reliable data flow also enhances your ability to manage large volumes of information effectively. It reduces the risk of errors during data collection and transformation, which could otherwise lead to flawed outcomes.
Tip: Regularly monitor your data pipeline to identify and resolve bottlenecks before they escalate. This proactive approach ensures uninterrupted data flow and minimizes downtime.
Role in Decision-Making
Data pipeline management plays a pivotal role in empowering decision-making processes. When your data pipeline operates efficiently, it delivers accurate and timely information to decision-makers. This enables you to analyze trends, assess risks, and make informed choices that drive business success.
Here’s how reliable data flow impacts decision-making:
- Managing large volumes of data effectively enhances your ability to analyze content and assess risks.
- Overcoming data overload ensures that critical insights are not lost in the noise.
- Implementing robust data strategies improves knowledge retention, making essential information readily available.
For example, a retail business can use a well-structured data pipeline to analyze customer purchasing patterns. This insight allows you to adjust inventory levels and optimize sales strategies. By ensuring that your data pipeline delivers high-quality information, you can make decisions that align with your business goals.
Impact on Operational Efficiency
Effective data pipeline management significantly boosts operational efficiency. By automating processes like data ingestion, transformation, and storage, you can reduce manual errors and save valuable time. This efficiency translates into faster data processing and retrieval, enabling you to respond quickly to business needs.
Consider these measurable impacts of a well-managed data pipeline:
- Improvements in data processing time and retrieval speed.
- Reduced error rates in data entry and cleanup tasks.
- Enhanced data integration efficiency, making it easier to combine information from various sources.
- Lower data duplication rates, ensuring cleaner and more reliable datasets.
For instance, automating data validation tasks can streamline your operations and free up resources for more strategic activities. Additionally, adhering to data governance policies ensures compliance and reduces the risk of security breaches. By focusing on these aspects, you can create a data pipeline that supports your organization’s growth and adaptability.
Note: Regular training on data governance policies can further enhance your team’s ability to manage data effectively, ensuring long-term operational success.
Benefits of Effective Data Pipeline Management
Improved Data Quality
Effective data pipeline management ensures that your data remains accurate, consistent, and reliable throughout its journey. By implementing robust processes, you can address common challenges like duplicate records, missing information, or outdated entries. This improves the overall quality of your data, making it more valuable for analysis and decision-making.
Key metrics help you evaluate these improvements. For example:
- Timeliness: Ensures your data stays relevant by measuring its age in the database.
- Uniqueness: Tracks and eliminates duplicate entries to maintain data integrity.
- Validity: Confirms that your data adheres to predefined standards.
| Metric | Description | Importance |
|---|---|---|
| Throughput | Amount of data processed per unit of time. | Indicates capacity for large volumes, crucial for real-time analytics. |
| Latency | Time taken for data to travel through the pipeline. | Critical for operations requiring immediate analysis. |
| Error Rate | Frequency of errors during data processing. | High rates suggest issues with data integrity. |
| Processing Time | Duration of processing individual data units or batches. | Reflects operational efficiency in converting data into insights. |
By focusing on these metrics, you can ensure that your data pipeline management system delivers high-quality data, enabling better insights and outcomes.
Faster Insights and Decision-Making
A well-managed data pipeline accelerates the flow of information, allowing you to gain insights quickly. Automation plays a key role here, reducing manual errors and speeding up data processing. This agility enables you to respond to market changes and make informed decisions faster.
For instance:
- Automation improves data accuracy, minimizing human errors and ensuring reliable data for decision-making.
- Faster data processing allows you to analyze trends and adapt strategies in real time.
Businesses like McDonald's have leveraged data pipelines to aggregate information from franchise locations. This approach enables them to analyze sales performance, customer preferences, and operational efficiency, leading to actionable insights. By adopting similar strategies, you can enhance your decision-making capabilities and stay ahead in competitive markets.
Cost Savings and Resource Optimization with FineDataLink
Data pipeline management tools like FineDataLink offer significant cost-saving benefits. Automation reduces manual tasks, allowing your team to focus on strategic initiatives. This improves productivity and optimizes resource allocation. For example, a manufacturing company reduced its data processing time by 40% through automation, enabling engineers to concentrate on innovation rather than tedious data handling.
FineDataLink enhances scalability and performance, helping you manage data spikes effectively. Its real-time synchronization capabilities ensure seamless data integration, reducing errors and improving reliability. Additionally, the platform simplifies workflow management, breaking down data silos and streamlining complex processes. These features not only save costs but also enhance operational efficiency.
By using FineDataLink, you can build a robust data pipeline management system that supports your business growth while minimizing expenses. Its advanced features make it an ideal choice for organizations looking to optimize their data strategies.
Real-World Applications of Data Pipeline Management
Data pipeline management plays a pivotal role in various industries, enabling organizations to harness the power of data for improved decision-making and operational efficiency. Let’s explore how it transforms key sectors like finance, healthcare, and e-commerce.
Finance
Fraud Detection
In the finance industry, real-time data pipelines are indispensable for fraud detection. They continuously monitor transaction data as it flows through the system, identifying patterns and anomalies that may indicate fraudulent activities. For example, if a credit card transaction occurs in two different locations within minutes, the pipeline flags it for review. This proactive approach helps financial institutions prevent fraud before it impacts customers.
Key Applications:
- Managing financial transactions with accuracy and speed.
- Detecting unusual patterns in real-time to mitigate risks.
Risk Analysis
Data pipeline management also enhances risk analysis by consolidating data from multiple sources. Financial institutions use pipelines to process historical and real-time data, enabling them to assess credit risks, market trends, and investment opportunities. For instance, a bank might analyze customer credit histories alongside economic indicators to make informed lending decisions. This ensures better risk management and improved financial stability.
Healthcare
Patient Data Management
In healthcare, data pipeline management ensures seamless patient data handling. Pipelines standardize and transform data from various sources, such as electronic health records and diagnostic devices. This data is then visualized through dashboards, helping healthcare providers make informed decisions. For example, a hospital can track patient admissions and equipment availability in real-time, reducing delays in care.
Benefits:
- Improved treatment outcomes through efficient data processing.
- Enhanced operational efficiency with standardized data visualization.
Predictive Analytics
Predictive analytics in healthcare relies heavily on robust data pipelines. By analyzing historical patient data, pipelines help predict potential health issues, enabling early intervention. For instance, a healthcare provider might use predictive models to identify patients at risk of chronic diseases. This approach not only improves patient care but also optimizes resource allocation.
E-Commerce
Personalization and Recommendations
E-commerce platforms use data pipeline management to deliver personalized shopping experiences. Pipelines process customer data, such as browsing history and purchase behavior, to generate tailored recommendations. For example, if you frequently buy fitness gear, the platform might suggest related products like yoga mats or protein supplements. This personalization enhances customer satisfaction and boosts sales.
Inventory Management
Efficient inventory management is another critical application in e-commerce. Data pipelines provide real-time insights into stock levels, helping businesses avoid overstocking or stockouts. For instance, during peak shopping seasons, pipelines adapt to varying data loads, ensuring timely restocking. This flexibility ensures smooth operations and customer satisfaction.
| Benefit | Description |
|---|---|
| Easy access to business insights | Facilitates quick retrieval of important data for analysis. |
| Faster decision-making | Enables timely responses to market changes and customer needs. |
| Flexible and agile | Adapts to varying data loads, especially during peak times. |
Data pipeline management empowers e-commerce businesses to stay competitive by streamlining operations and enhancing customer experiences.
Manufacturing
Supply Chain Optimization
Data pipeline management plays a crucial role in optimizing supply chain processes. By automating data movement and ensuring quality, you can streamline operations and make informed decisions. Optimized pipelines improve the speed and accuracy of data analysis, enabling you to respond quickly to market demands. For example, you can track inventory levels in real-time and adjust procurement strategies to avoid stockouts or overstocking.
Efficient data pipelines reduce redundancy and enhance data quality. This leads to better data management and more reliable insights. Automating these pipelines also minimizes mistakes, as built-in error detection mechanisms ensure consistency in data flows. With these improvements, you can process and analyze large data volumes efficiently, transforming raw data into actionable insights.
Benefits of supply chain optimization through data pipelines:
- Faster and more accurate data analysis.
- Reduced errors and improved data consistency.
- Enhanced decision-making with automated processes.
By leveraging data pipeline management, you can create a seamless flow of information across your supply chain, improving efficiency and reducing costs.
Real-Time Production Monitoring
Real-time production monitoring relies heavily on robust data pipelines. These pipelines collect and process data from sensors, machines, and other sources on the factory floor. This allows you to monitor production metrics, such as equipment performance and output rates, in real-time. For instance, if a machine shows signs of malfunction, the pipeline can alert you immediately, preventing costly downtime.
Data pipeline management ensures that production data remains accurate and up-to-date. This accuracy helps you identify inefficiencies and optimize workflows. Additionally, real-time monitoring enables you to maintain consistent product quality by quickly addressing deviations in the production process.
Key advantages of real-time production monitoring:
- Immediate detection of equipment issues.
- Improved workflow efficiency.
- Consistent product quality through timely interventions.
With data pipeline management, you can transform your production processes into a well-oiled machine, ensuring reliability and efficiency.
Other Industries
Public Sector: Data-Driven Governance
In the public sector, data pipeline management supports data-driven governance initiatives. By integrating and processing data from various sources, you can enhance transparency and improve decision-making. For example, the USDA secured funding for its Enterprise Data Governance program by demonstrating improved data quality for agricultural research. Similarly, the CDC created a shared dashboard to track COVID-19 infection rates, streamlining decision-making and enhancing public trust.
| Agency | Initiative Description |
|---|---|
| USDA | Improved agricultural research through better data quality. |
| CDC | Developed a COVID-19 dashboard for real-time tracking. |
| EPA | Published open data plans to enhance transparency. |
| DOT | Linked accountability to mission outcomes for better collaboration. |
These examples highlight how data pipeline management can drive impactful governance initiatives, ensuring data consistency and accessibility.
Retail: Enhancing Customer Experience with FineBI
In retail, data pipeline management enhances customer experiences by providing actionable insights. Tools like FineBI enable you to analyze customer behavior and preferences, helping you deliver personalized recommendations. For instance, if a customer frequently purchases fitness products, your system can suggest related items like yoga mats or protein supplements.
You can try it out in the demo model below:
FineBI also supports real-time data analysis, allowing you to monitor sales trends and adjust strategies promptly. This agility ensures that you meet customer demands effectively, even during peak shopping seasons. By integrating data from various sources, FineBI creates a unified view of your operations, helping you make data-driven decisions.
Benefits of using FineBI in retail:
- Personalized shopping experiences for customers.
- Real-time insights into sales trends.
- Improved operational efficiency through data integration.
With FineBI and effective data pipeline management, you can stay ahead in the competitive retail landscape, delivering exceptional value to your customers.
Data pipeline management is essential for modern businesses aiming to thrive in a data-driven world. It ensures timely and accurate data flow, enabling you to make informed decisions that drive growth and customer satisfaction. By automating processes, it improves operational efficiency, freeing up resources for strategic initiatives. Moreover, effective data management mitigates risks by ensuring data accuracy and compliance, protecting your business and maintaining trust.
Consider adopting solutions like FineDataLink and FineBI to streamline your data processes. These tools help you capitalize on real-time data, scale with agility, and consolidate information for strategic decisions. With robust data pipeline management, your organization can unlock new opportunities and achieve sustainable success.
Click the banner below to also experience FineDataLink for free and empower your enterprise to convert data into productivity!
Continue Reading About Data Pipeline
Mastering Data Pipeline: Your Comprehensive Guide
How to Build a Spark Data Pipeline from Scratch
Data Pipeline Automation: Strategies for Success
Understanding AWS Data Pipeline and Its Advantages
Designing Data Pipeline Architecture: A Step-by-Step Guide
How to Build a Python Data Pipeline: Steps and Key Points
FAQs on Data Pipeline Management
What is the purpose of data pipeline management?
Data pipeline management ensures your data flows efficiently from source to destination. It helps you process, transform, and store data accurately, enabling better decision-making and operational efficiency.
How does data pipeline management improve data quality?
It improves data quality by automating processes like cleaning, validation, and transformation. This ensures your data remains accurate, consistent, and ready for analysis.
Can data pipeline management handle real-time data?
Yes, it can. Real-time data pipelines process information as it arrives, enabling you to respond instantly to changes, such as detecting fraud or monitoring production.
What tools are commonly used for data pipeline management?
Popular tools include FineDataLink, Apache Airflow, and Talend. FineDataLink stands out for its real-time synchronization, low-code interface, and support for over 100 data sources.
Why is scalability important in data pipeline management?
Scalability ensures your pipeline can handle growing data volumes as your business expands. It prevents bottlenecks and maintains performance during data spikes.
How does automation benefit data pipeline management?
Automation reduces manual errors, speeds up processes, and ensures consistency. It allows you to focus on analyzing data rather than managing it.
What industries benefit most from data pipeline management?
Industries like finance, healthcare, e-commerce, and manufacturing rely heavily on data pipeline management. It helps them optimize operations, improve decision-making, and enhance customer experiences.
How can FineDataLink enhance your data pipeline management?
FineDataLink simplifies complex tasks with its low-code platform. It supports real-time synchronization, advanced ETL/ELT capabilities, and seamless integration with diverse data sources, making your pipeline efficient and scalable.